Funny, the word apparatchiks in English doesn’t need decryption

Funny, the word apparatchiks in English doesn’t need decryption
I recently read a Facebook post saying that if you break a thermometer, you must call the ghostbusters who will carry out the demercurization of the area and save your life. Crawling around with a piece of paper and gathering the beads is just foolery, apparently. It suggests that you can’t scrape it all up yourself, and only professional help can save the space and its inhabitants.
I decided to see what it’s like here. Everyone seems to be obsessed with such problems. Each similar incident is blown up to the scale of a cosmic problem and there is always a company offering professional help with the consequences. But somehow, mercury removal services are hard to find.
Just for fun, try to find at least one American organization that performs demercurization of premises. There is Poison Control, but as I understand it, they focus on giving the right advice and helping the caller if necessary. If you manage to find an organization (surely there must be one in the States), try to find their prices.
Yesterday we watched four episodes of Stranger Things in one go.
Interestingly, Netflix decided it was best to release all 10 episodes of Stranger Things 2 at once, rather than releasing them one per week. Apparently, subscription statistics show that the latter does not bring in more money than the former. And that’s quite fascinating. Think about it: watching all 10 episodes costs nothing (they give you a free month of subscription), or $7-14 per month if you’re paying. Releasing episodes weekly would have accustomed users to returning to the service, and likely would have pushed them beyond the free month with the series unfinished, which would have motivated them not to cancel the subscription. Meanwhile, there would have been heated discussions at water coolers and during kitchen breaks, which could have generated more buzz for the series. But the owners believe it is right to release all 10 at once. It’s interesting how much this decision is deliberate and calculated.
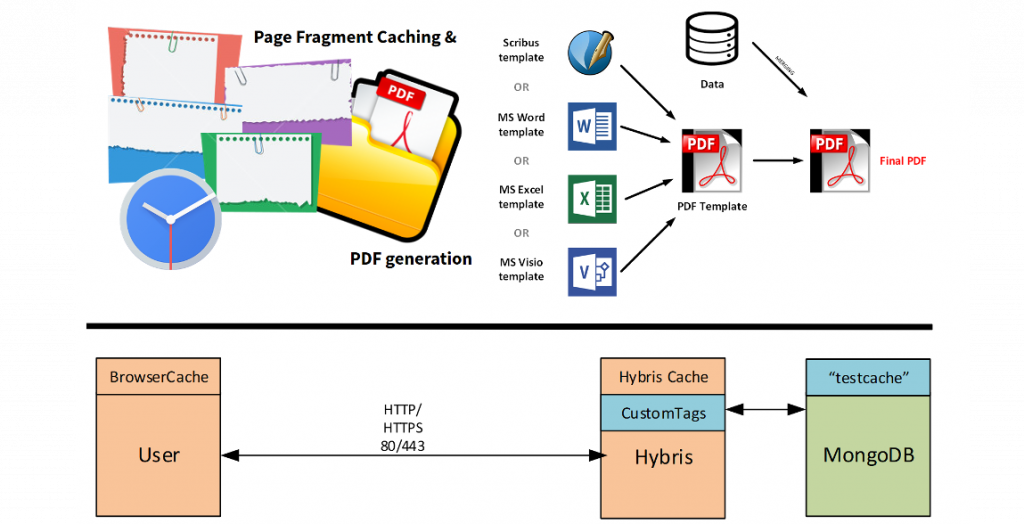
I released the sixth part of my presentation at SAP Moscow. This time I will talk about two topics: page fragment caching and PDF generation on the server using templates. The first experiment is explored in three variations: standard, using Varnish, and built on Nginx/Memcached. The second experiment also demonstrates several ways to solve the template-based PDF generation task. I discuss the pros and cons of these solutions, as well as reveal the implementation details.
Despite it ostensibly being about Hybris, the topics mentioned are not related to Hybris at all. They can be effectively used in any web system.
Welcome)
Yesterday we watched “Your Name” by Makoto Shinkai. A very beautiful animation, I recommend it. Romance, beautiful Japanese scenery, just as usual with Shinkai. The plot is a bit stretched and raises a bunch of questions, but that’s not very important, the film sets both the mood and the atmosphere well.
I believe that in a few years a new business will emerge, similar to today’s cryptocurrency mining, but focused on recognizing data from real-world sensors, such as video images or audio clips. Some Google or Yandex will be able to perform primary classification of objects, using their vast cluster with a neural network to determine that a picture shows a crocodile and a face. Third-party “contractors” will be able to focus on recognizing types of crocodiles or facial expressions, earning money from this specialization. Of course, for the first example, the neural network will need to be trained on crocodiles, and nothing else. Since there are very many object classes, a single, even large network owned by a giant like Google or Yandex will not be capable of handling everything, but it can “outsource” correctly: to another company that has a narrow specialization, and together they will provide the client with the best result.
Theoretically, recognition tasks can be assigned to more than one “contractor” and the results can be merged. For example, face recognition might be performed on different networks, trained on different races and nationalities. If the prediction of the contractor’s network turns out to be incorrect, their rating decreases, if it is confirmed – it increases.
Most likely, the system will not be structured as a tree with Google or Yandex at the top, and smaller companies below, but also as a network, where one company enriches the input stream with new knowledge, which helps the neighboring network to perform its specialized work better. For instance, understanding a crocodile’s breed might narrow down the recognition of the face of the aboriginal standing next to it, since breeds are tied to localities.
What do you think?
A very interesting lecture by Akunin in Amsterdam (in English). Boris Akunin pondered why whatever we build in Russia, it always ends up as a lack of free will with elements of folk dance. And if a writer asks a question, he usually writes a book about it” (с). And Akunin wrote 5 books “The History of the Russian State” (I have read two of them). He says that by the third book, a pattern began to emerge.”
“According to Akunin, the cycle that our long-suffering country experiences at every stage (totalitarianism — weakening — attempt at liberalization — reaction — totalitarianism) is linked to the fact that we constantly return to the khanate model of governance”
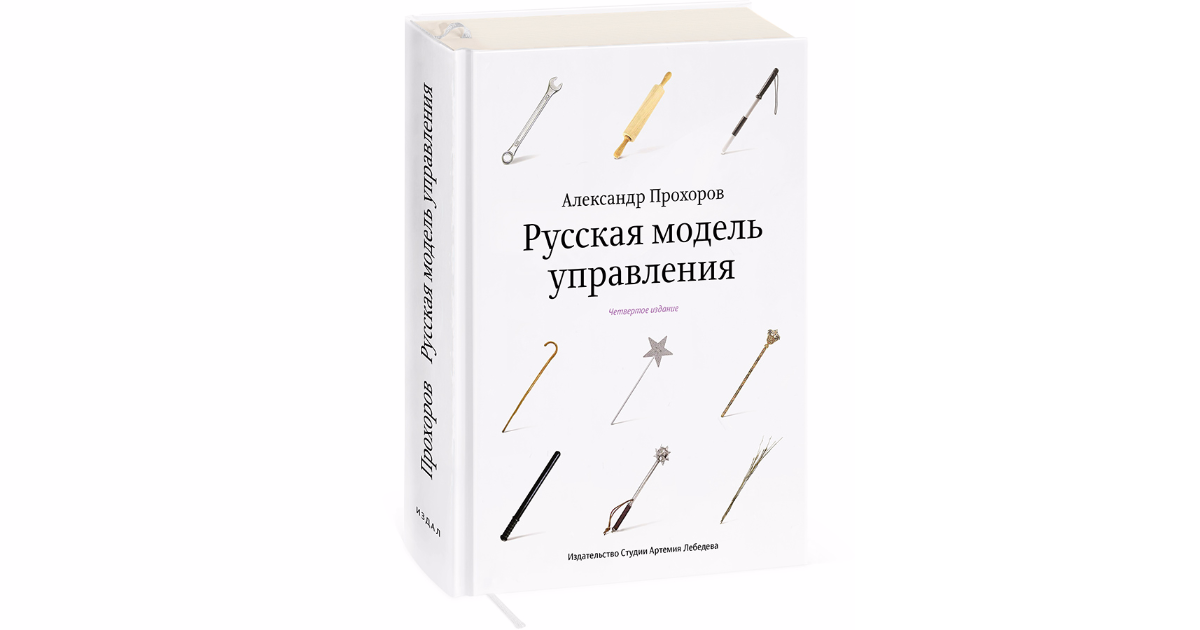
A very interesting lecture indeed. And a nice addition to the book “Russian Management Model” by the economist Alexander Prokhorov (
The biggest plus from the blockchain hysteria is that it promotes the growth of the “advanced programming” market: mathematics and algorithms, cryptography and security, resource constraints. Historically, these areas required much more fundamental preparation. Now, the hype has drawn young talents into this field. As a result, in a few years, we will see systems whose logic will be very difficult or impossible to explain simply. This has already happened in physics, in mathematics too, and not yet in programming.
Today at school, Masha had a curl-up test, doing torso lifts from a lying position counting each one. Every quarter all classes participate. She had to do at least seven, but a normal count is about 35-40 http://www.exrx.net/Testing/YouthNorms.html.
Masha did it 300 times today 🙂 A boy came in second with 250 or so. The whole school waited half an hour while Masha finished her 300)
My print background has shaped my taste in text layout, but for some reason it’s not shared by a multitude of designers around the world. Now tell me, do you also think that the typesetting in the first image is ridiculously wide and unreadable? Unfortunately, every second website is like this now.
The width of the column is inseparably linked to the font size. The ideal width for typesetting is about 55 to 75 characters. Not 150, like in the first image.
Leading is a function of point size, line length, and format. The longer the line in terms of word count, the greater the leading should be. Usually, it is a few points (2-5) more than the font size, depending on the font and the width of the text. For extreme widths (75 characters), you can confidently increase the leading up to +10pt (max) to make it easier to read. Or you can multiply by 1.2…1.3 for the web — for the majority of sizes it will look neat and pleasant. 1.2 for narrow setting (55 characters), 1.3 – for wide (75 characters).
The ratio of line length to leading should be about 25. In my example, it’s 900px / 25 = 36px – that’s the leading. Dividing by 1.3, we get ~29px. This is the font size.
In Word, there are no pixels, there it’s width in centimeters, and font size is in points. To understand which font is ideal, you need to convert the typesetting width (let’s say, 16 cm) to points by multiplying by 28.3 (which gives 452pt), and then divide by 25 (which gives 18pt). This is the leading. To find the font size, divide by 1.2, giving 15pt. I attach the result as the third image.
Here’s a good calculator with a preview of the result: